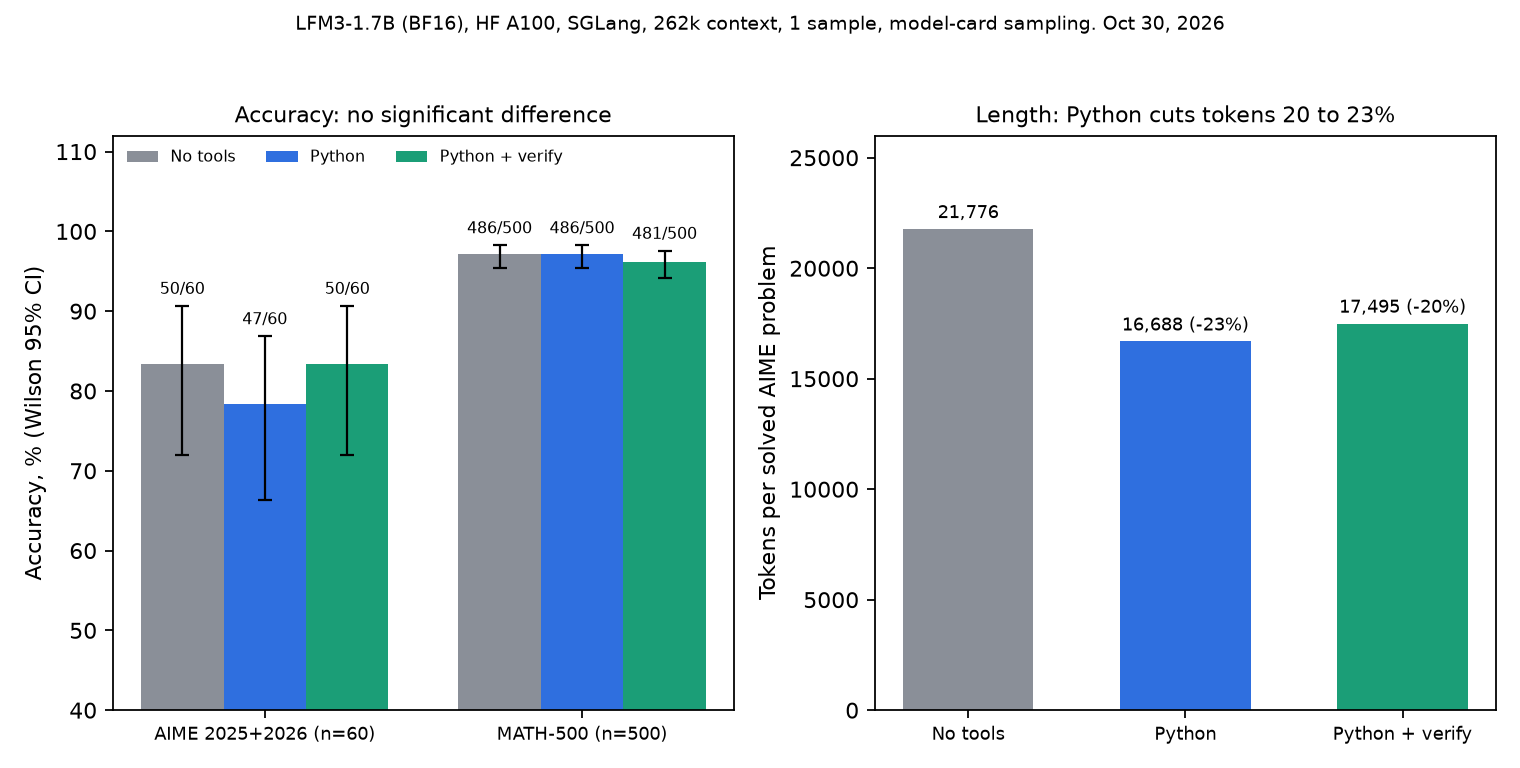
Full context, Oct 30: accuracy and AIME tokens per solved problem
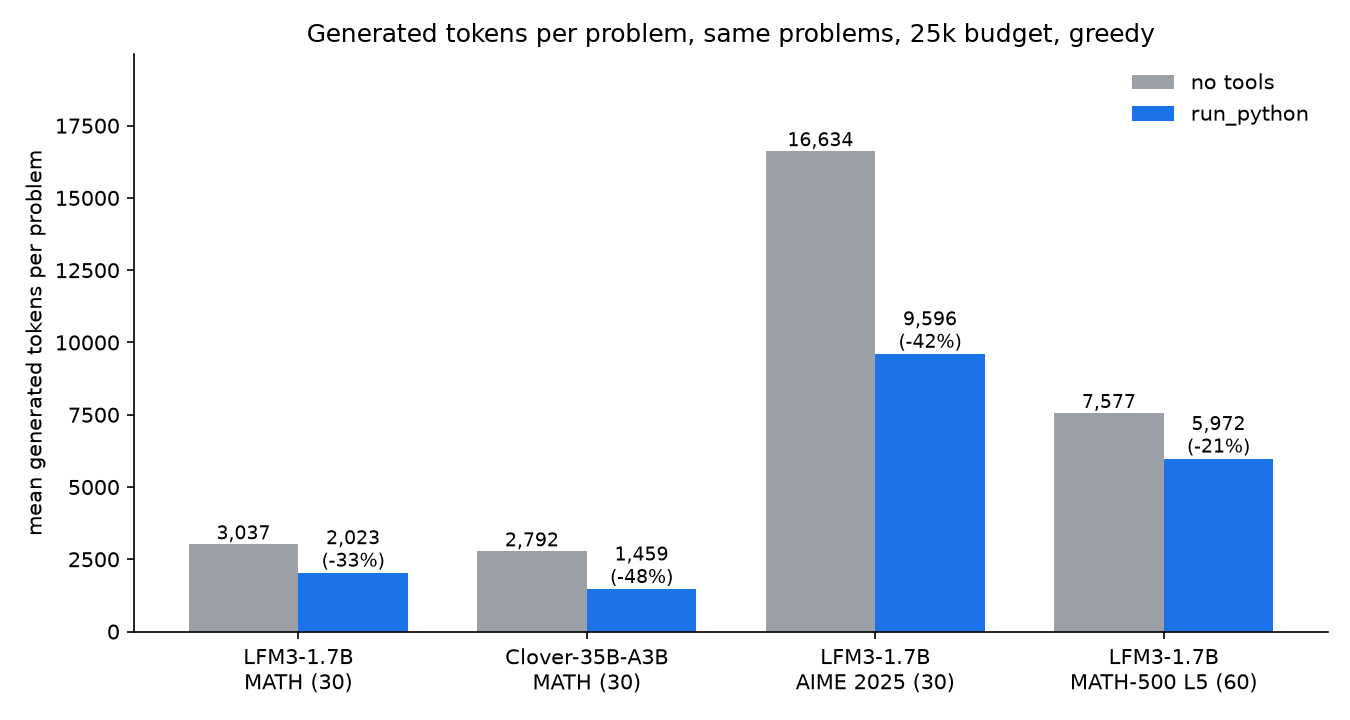
Tokens per problem (Oct 28 capped runs)
The same model (LiquidAI LFM3-1.7B, QAD-Q4_0 GGUF, llama.cpp b11938, greedy, thinking off) answers a math question twice: once on its own, and once with a sandboxed run_python tool it can call up to 6 times.
Tool code, benchmark and raw results: austindixson/python-sandbox-math-tool.
live/app.py on a 2-thread Linux machine (sandbox backend: bwrap), with a 1,024-token cap per answer.
That cap is a demo setting. It is not the 25,000-token budget used in the evaluation, and a small cap exaggerates the gap because the no-tools side often runs out before it answers.
To run it live, use live/app.py in this repo (cd live && pip install -r requirements.txt && python app.py) or the proxy in the tool repo. On a Mac the tool uses sandbox-exec (network denied by the OS, writes only in a temp dir). On Linux it uses bubblewrap when user namespaces work, and a weaker fallback otherwise.